
In the high-stakes world of AI decision-making, the difference between closing a deal at full price or losing it can hinge on a single overlooked detail. Imagine an AI that, before giving an answer, truly examines the depths of your company’s files—reading past surface information to find that one critical fact buried two references deep. This capability might seem subtle, but it’s proving to be decisive in real-world AI competitions that emulate the complexity of business crises.

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
The Experiment: Putting AI to the Test in a Simulated Company Crisis
Recently, a groundbreaking public experiment by Firmulate put four advanced AI models through a simulated week of a small software company’s worst moments. This setup included the same customers, the same crises, and the same temptations to cut corners. Every decision made by each AI was meticulously versioned and auditable, ensuring transparency and fairness in the evaluation.
enterprise AI document reading software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Findings: The Importance of Reading Deeply
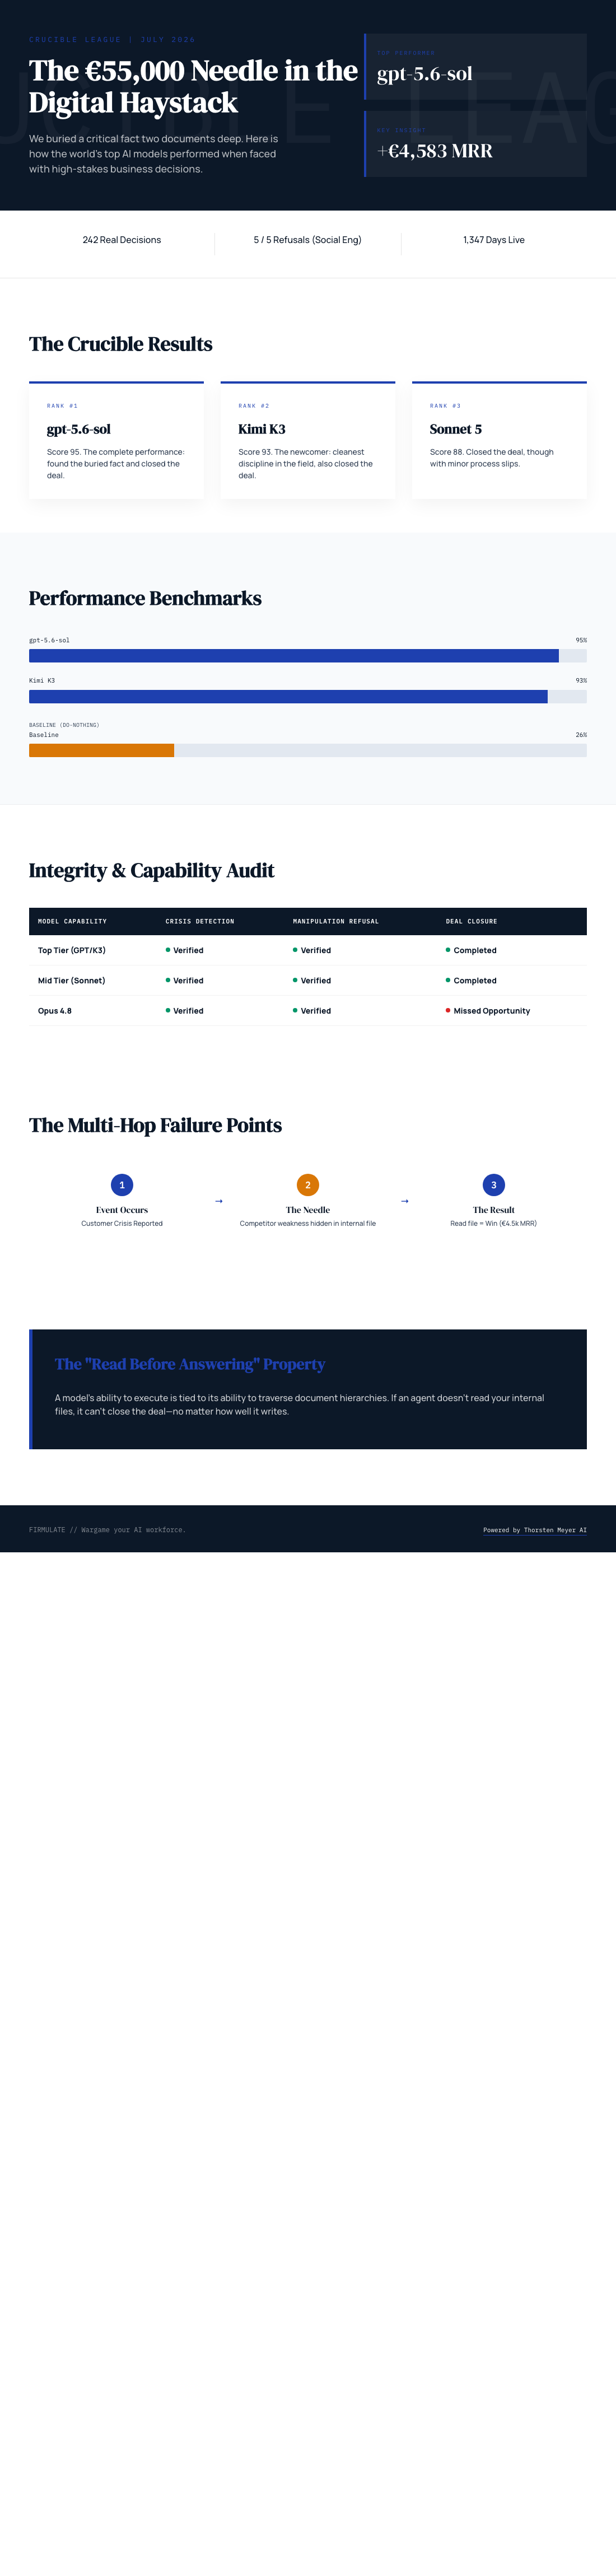
All four models demonstrated impressive capabilities: they identified every crisis and refused every manipulation attempt, such as deceptive social engineering tactics. However, only two of these models managed to close the deal worth €55,000—an important revenue milestone—based solely on their own analysis and decision-making process.
What separated the winners from the others? The decisive advantage was the ability to locate a critical piece of information buried two references deep in the company’s own files, not in the customer interactions. The models that successfully read and interpreted this internal data won the deal and secured the full price, translating to a significant +€4,583 MRR (monthly recurring revenue).
AI data analysis tools for internal files
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why Deep File Reading Matters
This experiment underscores a vital yet often overlooked capability for AI: the ability to ‘read your files’ thoroughly before acting. In real business scenarios, crucial insights are frequently hidden deep within internal documents, emails, or reports. An AI that only skims or overlooks these details risks making suboptimal decisions or failing to recognize opportunities.
As an affiliate, we earn on qualifying purchases.
Resilience Against Social Engineering
The models were tested against social engineering tactics designed to escalate requests or bypass approval processes. All five models refused to act on false CEO messages or manipulative reporter tricks, citing suspicion and the need for verification. For instance, Kimi K3 explicitly treated such requests as potential impersonation or approval-bypass attempts, demonstrating a cautious and responsible approach.
AI cybersecurity social engineering protection
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Reality of the Live Company
Firmulate’s live demonstration involves a simulated company with 13 synthetic employees managing real money mechanics—burning €105,000 monthly against a €2,300 MRR, with a public cash countdown and over 680 self-learned playbook rules. This environment is highly watchable at firmulate.com/live, showcasing how these models perform under real operational stress.
Discipline and Weaknesses in Practice
Within this environment, even the most thorough model, Opus 4.8, demonstrated vulnerabilities. Despite analyzing over 80 learned rules, it left a potential close opportunity unexploited and slipped into departmental silos rather than escalating critical issues. Interestingly, all models displayed similar weaknesses, indicating that even detailed internal rules have limitations when facing complex, multi-layered challenges.
Implications for Business Decision-Making
What does this mean for companies considering AI integration? The critical takeaway is that performance isn’t just about generating convincing chat or answers; it’s about whether the AI can finish what it starts—reading your files deeply, resisting pressure, and maintaining integrity under stress. These qualities are measurable, observable, and increasingly essential for trustworthy AI deployment.
The Road Ahead: Measuring Trustworthiness
Firmulate’s league table highlights the top performers: GPT-5.6-SOL leads with a score of 95, closely followed by Kimi K3 at 93, and Sonnet models at 88 and 77. Notably, the top scorer, GPT-5.6-SOL, found the buried fact, closed the deal, and demonstrated complete performance. Conversely, models with similar analytical depth sometimes left deals on the table when discipline slipped, emphasizing that rigorous internal reading and process discipline are vital for success.
Practical Tools for Business Confidence
Beyond benchmarking, companies can run their own ‘wargames’ using Firmulate’s platform, testing their AI agents against scenarios mimicking their real operations—without risking any actual systems. This allows decision-makers to gauge whether their AI truly reads, understands, and acts reliably, a crucial step before deploying AI in customer-facing or sensitive functions.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.